
The institutional challenge
Artificial intelligence presents regional cooperation with a practical opportunity: reducing the time spent on routine administrative work and making institutional knowledge easier to use. For institutions responsible for coordinating national interests, however, adopting AI also raises questions about confidentiality, independence, and trust.
The pace of development helps explain the urgency. In September 2026, Scientific American reported OpenAI’s claim to a major mathematical breakthrough, alongside a dispute about the work’s origins.1 Current and former employees of leading AI companies have also called for stronger protections for those who raise concerns about advanced AI, including the possibility of losing control of autonomous systems.2 Meanwhile, the Wall Street Journal has reported on the Trump administration’s preference for limited regulation, framed in part around competition with China.3 These developments show how closely technical progress, public accountability, and geopolitical competition have become connected.
This article focuses on regional or sub-regional intergovernmental organizations whose membership does not include a state at the forefront of developing the most advanced general-purpose AI models. For brevity, these are referred to throughout as “organizations.”
The absence of such a member state should not be confused with an absence of regional expertise. The challenge is how an organization can obtain useful AI capabilities while retaining control over its information and respecting the interests of all its members.
Locally hosted open-weight AI offers a practical way forward. It allows an organization to run an existing AI model on hardware under its control and adapt the surrounding system to its work. For organizations handling sensitive deliberations, this approach deserves serious consideration as part of their institutional infrastructure.
Why these organizations face a particular dilemma
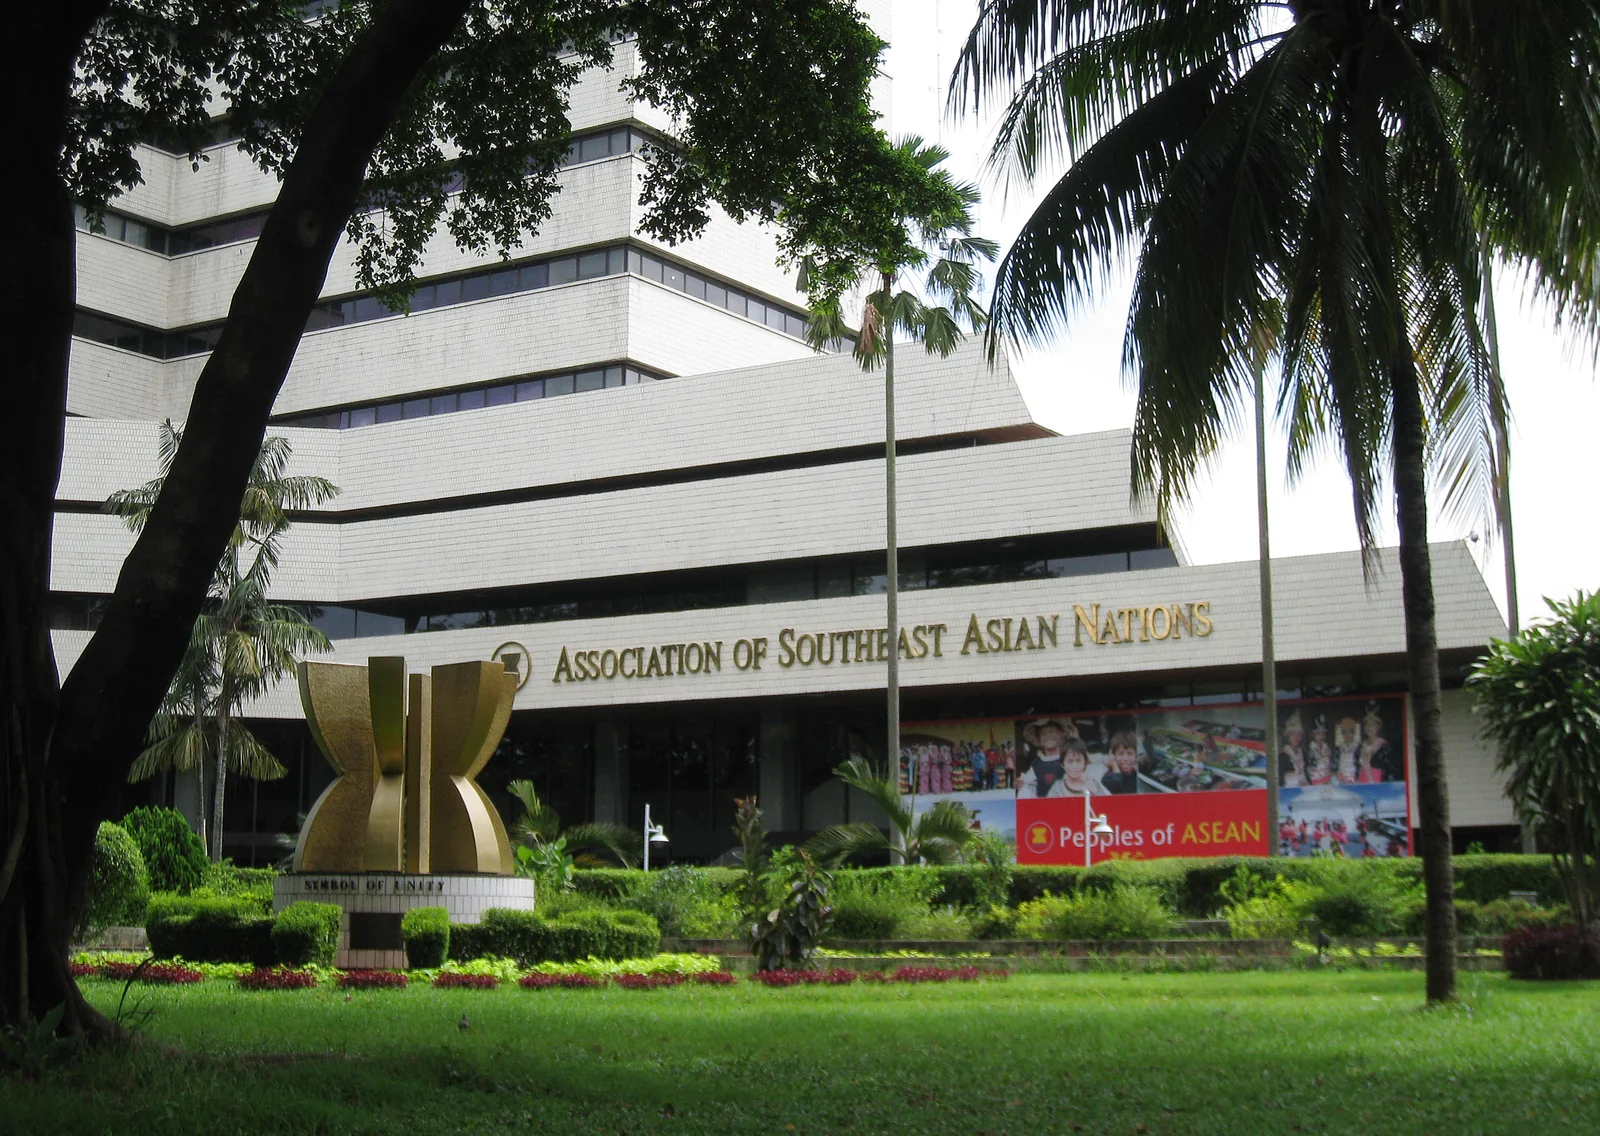
The work of bodies such as the African Union, the Association of Southeast Asian Nations, the Andean Community, and the Caribbean Community illustrates the potential value of AI. Their responsibilities include coordinating policy, supporting trade, aligning standards, and maintaining records across numerous areas of cooperation.
AI could assist with preparing draft meeting minutes, comparing policy documents, locating earlier decisions, and organizing correspondence. These tasks are especially relevant to secretariats, where staff must work across extensive records and preserve continuity between meetings, officials, and successive programmes of work.
Yet the same records may contain negotiating positions, unpublished proposals, or sensitive discussions concerning political and security matters. Their value depends partly on the confidence that member states place in the organization’s handling of them.
Cloud-based AI services process requests on a provider’s computers. Their convenience must therefore be weighed against questions about who can access information, where it is processed, how long it is retained, and which legal and contractual arrangements govern its use.
These services offer different protections. Some enterprise offerings restrict the use of customer data for model training and provide controls over retention. The details of the service and its configuration matter, as Google Cloud’s published data policies illustrate.4
Nevertheless, an organization may need stronger assurances than a commercially acceptable privacy policy. Its members may have different relationships with the countries in which providers operate, different security concerns, and different views about acceptable dependence on external suppliers.
Developing a new model to compete with the world’s leading AI systems would, meanwhile, demand resources and expertise beyond what many secretariats could reasonably commit. Agreeing on funding, ownership, and oversight could introduce further difficulties.
The resulting question is straightforward: how can an organization benefit from AI while retaining meaningful control over the information entrusted to it?
The case for open-weight models
An AI model is the underlying system that processes information and generates responses. A large language model, or LLM, is a type of model trained to process and generate language.
An open-weight model makes its learned numerical settings, known as weights, available for download. With suitable software and hardware, others can run the model themselves, subject to its licence.
“Open-weight” does not necessarily mean “open-source.” Access to the weights does not guarantee access to the training data or all the code used to develop the model, and licences may impose restrictions. The Open Source Initiative’s definition of open-source AI makes this broader distinction clear.5
For an organization, the practical advantage is that it can adopt an existing model without financing its original development. Many models are available without a licence fee, although running, maintaining, and adapting them still costs money.
There are also efforts to make models more useful in particular linguistic and cultural settings. AI Singapore’s SEA-LION initiative, for example, develops models intended to better represent Southeast Asian languages and contexts.6 Such work demonstrates that regional expertise can contribute meaningfully without requiring every organization to establish its own major AI research programme.
The appropriate model should be selected for the organization’s actual work. A system that reliably helps staff retrieve earlier decisions and prepare draft minutes may be more valuable than one with impressive general capabilities but poor performance on the organization’s languages, documents, or procedures.
An organization can also improve usefulness by giving the system controlled access to approved reference materials, providing templates, and refining its instructions. These changes do not necessarily require retraining the model.
Open-weight models therefore create room for gradual adaptation: an organization can begin with a limited function and expand as experience demonstrates what works.
Why local hosting matters
Open weights and local hosting address separate questions. Open weights concern access to the model; local hosting concerns where it runs. An open-weight model can also be operated by a cloud provider.
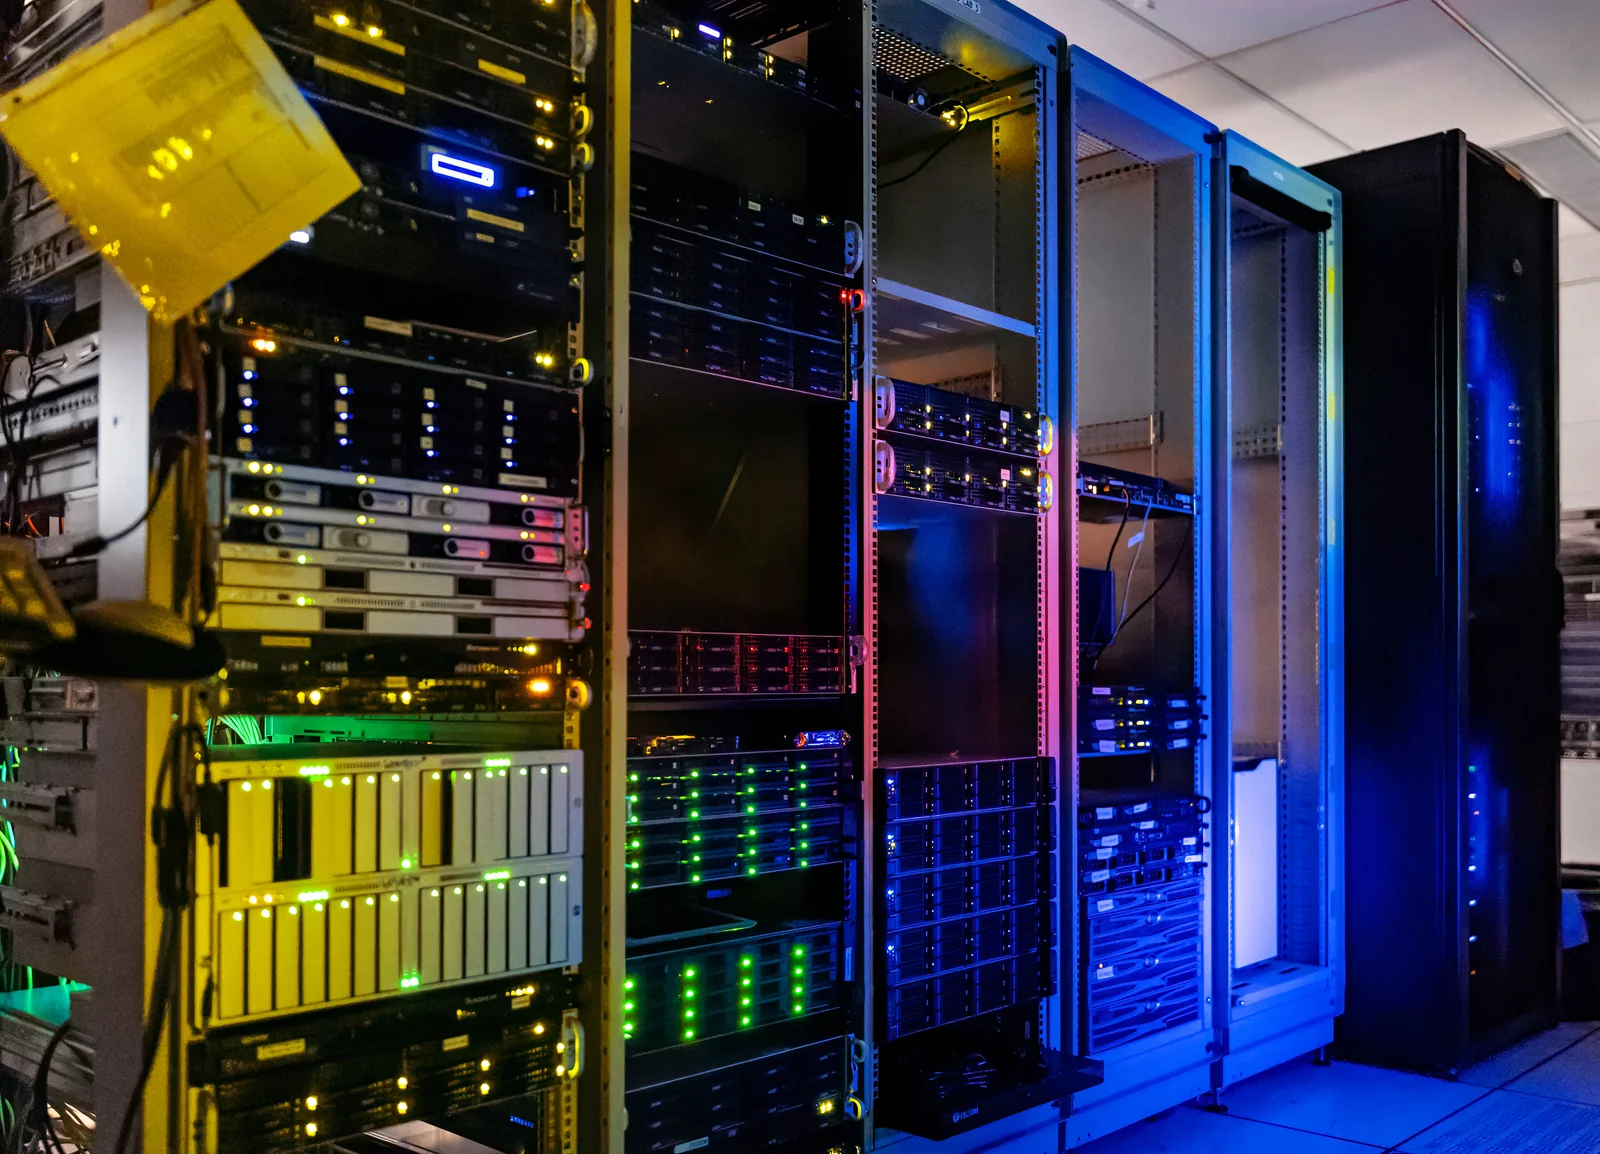

Here, locally hosted AI means a system running on hardware owned or directly controlled by the organization, within its own managed computing environment.
The strongest argument for this arrangement is institutional control. An appropriately configured system can process confidential documents without routinely sending their contents to an external AI provider. The organization can determine who uses it, which records it can consult, and how its operation is supervised.
That control must extend to the complete system. A locally running model offers limited protection if its document-processing tools, backups, or connected services still send sensitive information elsewhere. External support arrangements also need to specify whether technicians can access organizational data.
Hiring a provider based in a member state may address some concerns, but its location alone does not settle questions about access, ownership, oversight, or future changes in control. Any such arrangement should be assessed against the organization’s confidentiality requirements and the confidence of its membership.
The history of Crypto AG gives this concern a concrete precedent. Investigations into the Swiss encryption company exposed concealed links to foreign intelligence services and the sale of vulnerable encryption equipment to other states.7 For organizations evaluating suppliers, the lesson is to examine actual ownership, access, and oversight rather than rely on a provider’s national identity or reputation alone.
Local hosting brings responsibilities of its own. The organization must provide competent administration, security updates, access controls, backups, and reliable support. A poorly maintained internal system can expose information just as an unsuitable external service can.
The case for local hosting therefore rests on the ability to establish and sustain meaningful control. Ownership of the equipment is only one part of that task.
There is also a limit to what local hosting can achieve. A model developed elsewhere may still reflect assumptions or biases in its training. Keeping information inside the organization does not guarantee accurate or impartial answers. AI systems can produce convincing but false statements, a risk addressed in NIST’s guidance on generative AI.8 Staff must remain responsible for checking outputs, especially where wording could affect the record of a member state’s position.
For sensitive work, these considerations support treating local hosting as a serious institutional investment. Its value should include confidentiality, continuity, and accountability alongside the time it might save.
What decision-makers need to understand
Leaders do not need to become computer engineers to make a sound decision. They do need enough understanding to ask useful questions and assess the answers.
Model size and design
Models are often described by their number of parameters: the numerical settings learned during training. Parameter counts help indicate a model’s scale and computing requirements, but a larger number does not by itself establish that a model will perform better on a particular task.
Technical proposals may also distinguish between dense models and mixture-of-experts models. Broadly, dense models use most of their network for each processing step, while mixture-of-experts models activate selected parts. The latter can reduce computation while retaining a large overall model, although substantial memory may still be required. Mistral’s explanation of its Mixtral model illustrates this design.9
The relevant procurement question is how well the proposed model performs on representative organizational tasks using the proposed equipment.
Hardware capacity and speed
A computer needs enough memory to hold the model and process the material supplied to it. Proposals may refer to VRAM, memory used by a graphics processor, or unified memory, which different processors share.
Quantization reduces the numerical precision used to store a model, allowing it to use less memory. This can make operation on more modest hardware possible, although the effect on output quality must be tested.10
Speed depends on several factors, including the model, computing power, software, document length, and number of simultaneous users. Memory bandwidth, the speed at which data moves to and from memory, is one relevant factor.
A demonstration with one user and a short document is therefore insufficient evidence that the system will serve an entire secretariat.
Working with documents
The model is only one component of a usable AI service. Staff also need an interface and supporting software that can handle the materials they work with.
Text from many Word documents, presentations, and PDFs can be extracted and supplied to a language model. Scanned pages require optical character recognition, or OCR, to turn images of text into readable text. Interpreting charts, photographs, and complex page layouts may require additional visual capabilities.
A model without vision capabilities can still work with documents whose text has been extracted. The practical question is whether the complete system can reliably process the organization’s actual files.
Working context and institutional memory
A model’s context window is the amount of material it can consider while producing a response. It is useful to think of this as its working space: the instructions, conversation, and document passages available for the task.
A larger context window can accommodate more material, but it does not automatically provide a reliable memory of the organization’s records.
To answer questions about earlier meetings, the system needs a way to locate relevant records and supply them to the model. Those records must be organized, kept current, and subject to appropriate access restrictions.
For example, “Please prepare the latest meeting minutes” may leave several matters unresolved: which meeting, which source materials, and which approved format. A useful system should draw on available records and ask for clarification where needed. It should not invent the missing details.
Instructions and access
A system prompt is a set of standing instructions supplied to guide the model’s behaviour. For example:
You assist staff of the ASEAN Secretariat. Prepare draft meeting minutes using the supplied records and approved template. Identify the sources used, flag missing information, and do not invent decisions or attribute statements without evidence.
These instructions can improve consistency, but they cannot guarantee compliance or replace technical access controls.
The surrounding application, sometimes called a harness, provides the interface and connects the model to documents and tools. Its permissions should ensure that users can obtain only information they are authorized to access. Access to the AI service should not become a route around existing restrictions on confidential records.
Cost and practical value
Language models process text in tokens, which may be words, parts of words, or punctuation. Tokens are used for both input and output; they are not interchangeable with words.11
Technical comparisons may report cost per token or output speed in tokens per second. These measures are useful, but they do not capture the full cost or value of a service.
Local hosting requires expenditure on equipment, electricity, administration, maintenance, and eventual replacement. Cloud services may charge through subscriptions or usage-based fees.
An organization should also measure the time required to check and correct results. The more useful comparison is the cost of completing a task to an acceptable standard, including human review and the required protection of information.
A practical framework for implementation
Implementation should proceed through a manageable cycle of consultation, testing, evaluation, and improvement.
1. Establish the purpose and responsibilities
Begin with the work the organization wants to improve. Relevant staff, leadership, technical personnel, and those responsible for legal matters and information management should identify suitable tasks and agree on the boundaries of use.
This includes deciding which information the system may process, who may access it, who will maintain it, and who remains responsible for its outputs. Leadership should understand both the initial investment and the continuing operating costs.
Staff should also receive practical guidance on where the system can help and where human judgment remains essential.
2. Run a limited pilot
Start with a small number of tasks and users. Suitable consumer hardware may be sufficient for an initial trial, depending on the model and workload.
Use public or appropriately cleared material while the system’s operation and controls are being tested. Possible starting tasks include summarizing published documents, comparing versions of a text, or preparing draft minutes from approved sample records.
Record successes and failures systematically. Assess accuracy, missing information, response times, ease of use, and the amount of correction required. The pilot should establish what the system can reliably contribute under realistic conditions.
3. Compare proposed improvements
An organization’s divisions provide opportunities to understand different needs. A team working on trade documentation may require different support from one preparing meeting records.
Proposed changes can be tested with selected users before wider deployment. Where appropriate, A/B testing—comparing two versions of a system on comparable tasks—can help determine whether a change actually improves performance.
For example, one version might prepare draft minutes using only the meeting record, while another also receives relevant framework agreements and earlier decisions. Reviewers could then assess whether the additional material improves accuracy and usefulness.
Differences between departments should be taken into account; results from dissimilar tasks should not be treated as directly comparable.
4. Introduce improvements that demonstrate value
Once an improvement has been evaluated and approved through the organization’s agreed process, it can be introduced more widely.
Some improvements may require a different model or more capable hardware. Others may be simpler: clearer instructions, better document organization, an improved template, or additional user training.
Expansion should follow demonstrated usefulness and adequate operating capacity.
5. Repeat the cycle
Return to testing and evaluation as needs change. An organization’s documents, responsibilities, and working practices will evolve, as will the available models and software.
Continued improvement requires a recurring budget, identifiable responsibility, and a way for staff to report problems. Purchasing equipment and installing a model are the beginning of this process.
The cost of leaving the question unanswered
Leaders who remain unconvinced of the urgency should consider one question:
Do you know whether staff are already entering internal documents or sensitive information into unapproved cloud-based AI services?
The absence of an institutional decision does not necessarily mean the absence of AI use. Staff facing substantial workloads may seek readily available tools, particularly when no practical alternative or clear guidance exists.
A useful internal service, supported by clear rules and training, can give staff an approved way to obtain assistance while allowing the organization to supervise how its information is handled.
Locally hosted open-weight AI offers organizations a way to build capability at a manageable pace, drawing on existing models and regional expertise. With appropriate investment and oversight, it can support their work while preserving control over the records and deliberations entrusted to them.
For organizations whose effectiveness depends on the confidence of their members, that control is a substantive part of the value AI must deliver.
AI tools assisted with the research, editing, and formatting of this article. The central argument and views are the author’s own.
Notes and sources
- Joseph Howlett, “OpenAI claims blockbuster math breakthrough amid swirl of controversy”, Scientific American, 8 September 2026. The report describes a claimed advance and a dispute about its origins; it is cited here as an example of the pace and contested nature of AI developments. ↩
- Current and former employees of leading AI companies, “A Right to Warn about Advanced Artificial Intelligence”, 4 June 2024. The signatories identify risks, including loss of control of autonomous AI systems, and call for protections for people raising concerns. This is a statement of concern, not evidence that such a loss of control has occurred. ↩
- James Romoser, Meridith McGraw, and Amrith Ramkumar, “Trump Sees Race Against China as Key Issue on AI Regulation”, The Wall Street Journal. See also the White House, “Winning the Race: America’s AI Action Plan”, July 2025, on competition and the removal of regulatory barriers. ↩
- Google Cloud, “Gemini Enterprise Agent Platform and zero data retention”. Training restrictions, retention exceptions, and configuration requirements are service-specific; they should be checked against the offering being considered. ↩
- Open Source Initiative, “The Open Source AI Definition,” version 1.0. The definition addresses freedoms to use, study, modify, and share AI, together with the availability of necessary code and data information. ↩
- AI Singapore, “Southeast Asian Languages in One Network Data (SEALD)”, describing SEA-LION and work to improve language data and regional representation. ↩
- Imogen Foulkes, “Swiss machines ‘used to spy on governments for decades’”, BBC News, 11 February 2020. See also the Swiss Parliament’s announcement of the findings of its Crypto AG investigation, 10 November 2020. The example illustrates historical supplier and oversight risks; it is not an allegation about a contemporary AI provider. ↩
- National Institute of Standards and Technology, “Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile,” NIST AI 600-1, July 2024, particularly its discussion of confidently stated false information, harmful bias, and human oversight. ↩
- Mistral AI, “Mixtral of experts”. The distinction between total and active parameters explains why model size and computation requirements should be considered separately. ↩
- Hugging Face, “Quantization: Overview”, on reducing memory requirements by storing weights at lower numerical precision while seeking to preserve accuracy. ↩
- Hugging Face, “Tokenization algorithms”, on dividing text into tokens, including subword units. ↩